A paper has models declare which part of their memory to read, cutting attended tokens by half
Read the full description of this diagram
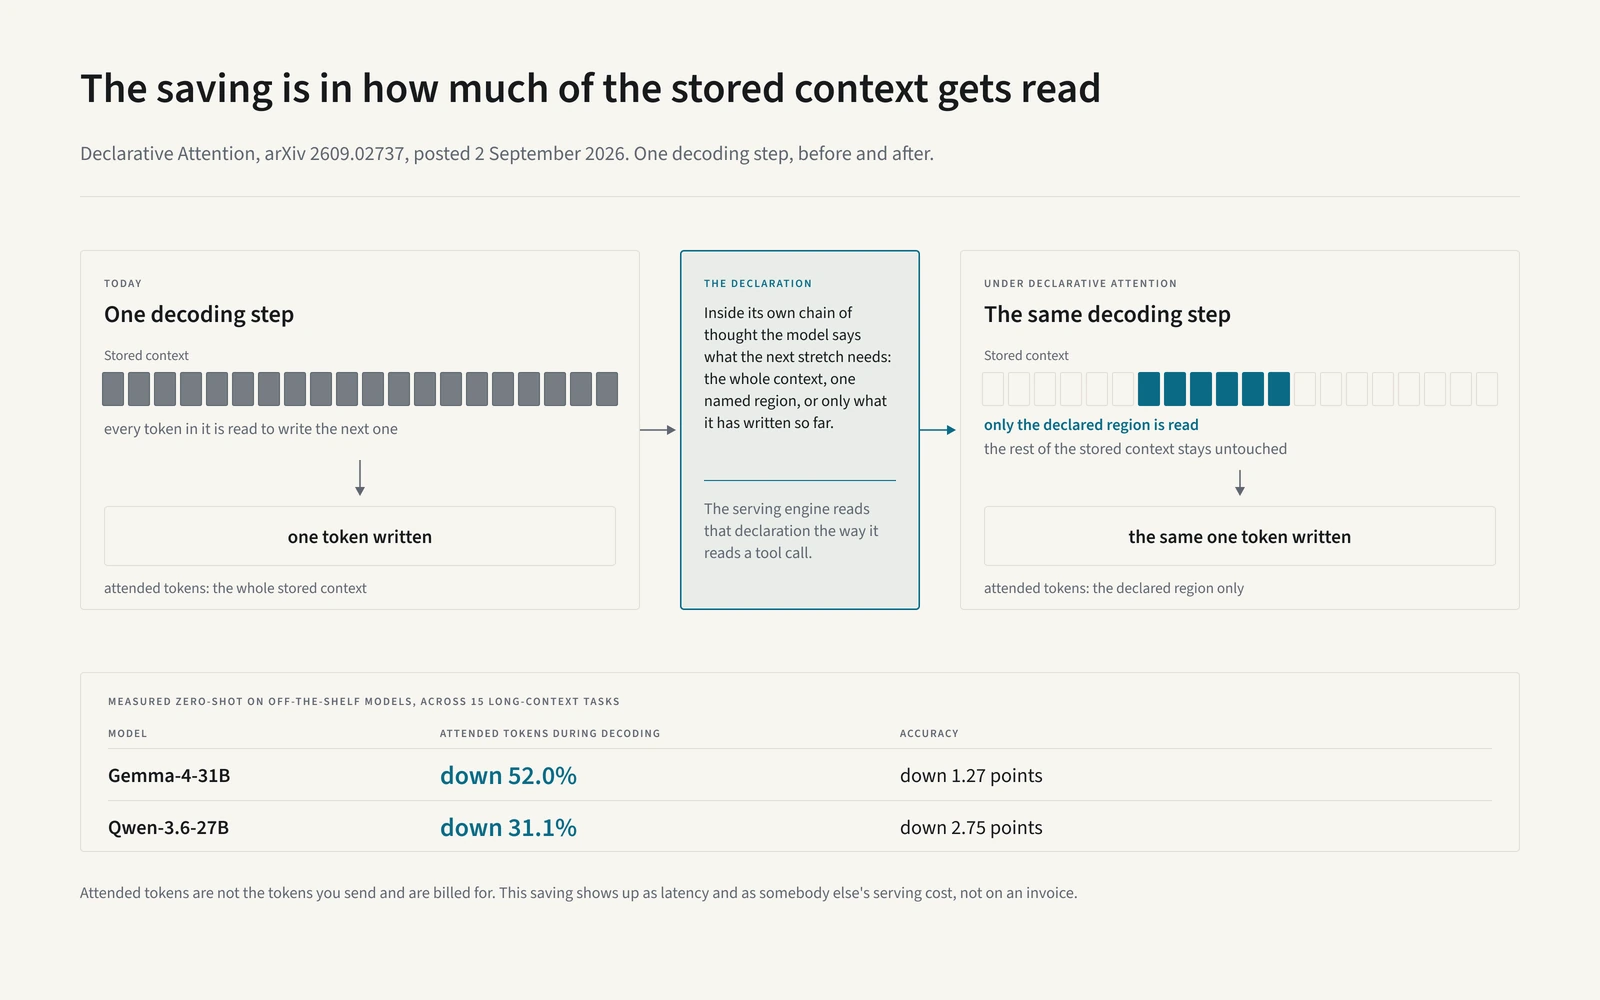
Two-panel diagram of one decoding step. On the left, every cell of a row standing for the stored context is filled, to show all of it being read to write a single token. Between the panels a box labelled the declaration says the model states inside its own chain of thought whether the next stretch needs the whole context, one named region, or only what it has written so far, and that the serving engine reads that declaration the way it reads a tool call. On the right, the same row has only a middle group of cells filled as the declared region while the rest stays untouched, and the same single token comes out. A table below records attended tokens during decoding down 52.0% on Gemma-4-31B and down 31.1% on Qwen-3.6-27B, for accuracy down 1.27 and 2.75 points.
A KAIST AI and Google DeepMind paper has models declare which part of their context to read, cutting attended tokens by 52.0% on Gemma-4-31B for a 1.27 point accuracy drop.
Read the itemResearch