What happened
Published here
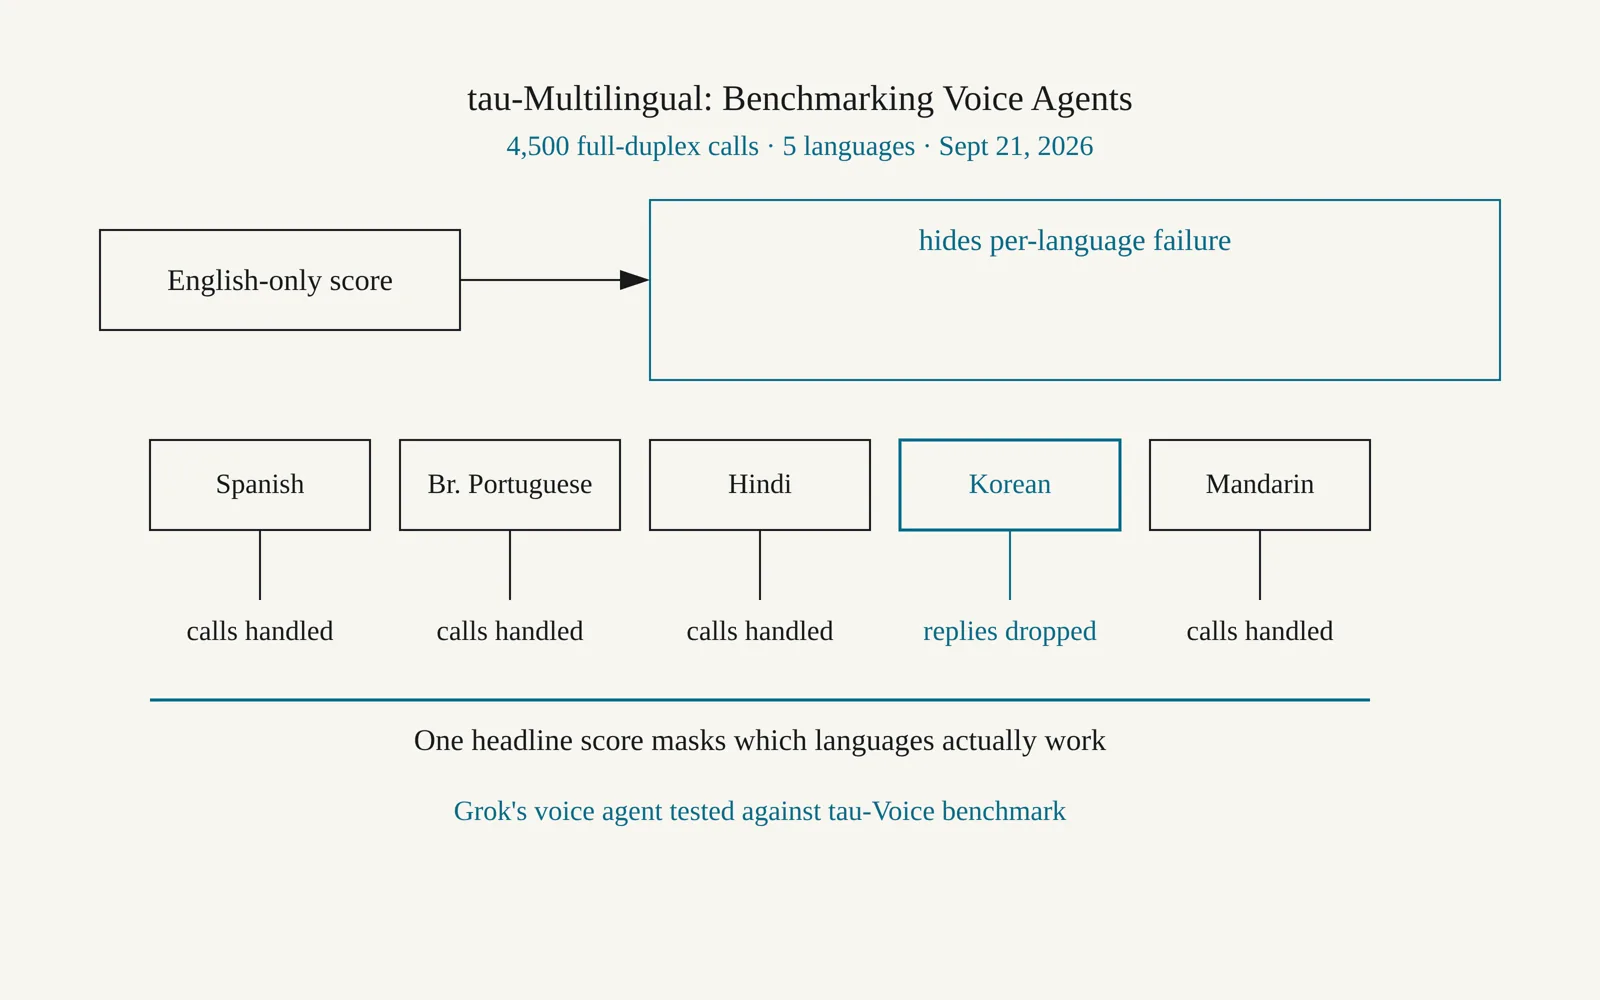
On September 21, 2026, researchers published tau-Multilingual, a paper extending the tau-Voice benchmark to Spanish, Brazilian Portuguese, Hindi, Korean and Mandarin, running 4,500 full-duplex calls across five voice configurations and grading task completion, interaction handling and generation quality separately for each system tested, including xAI's Grok. (arXiv paper, tau-Multilingual: Benchmarking Voice Agents Across Languages, submitted September 21, 2026)
Open the photograph at full size
Photograph: Diagram: AI Journey
Read the full description of this diagram
Diagram drawn for this item: Paper Benchmarks Grok's Voice Agent Across Five Languages. On September 21, 2026, researchers published tau-Multilingual, a paper extending the tau-Voice benchmark to Spanish, Brazilian Portuguese, Hindi, Korean and Mandarin, running 4,500 full-duplex calls across five voice configurations and... For a team picking a voice agent to handle calls outside English, a single English-only completion score now hides which languages actually work, so a vendor's headline number can mask a system that drops replies in Korean or talks over...
The numbers
Full-duplex calls
4,500
Calls run across five voice configurations
Korean completion drop
14.7
Task-completion points Korean fell below English
Mandarin completion drop
8.4
Task-completion points Mandarin fell below English
Near-English languages
3.2
Points Spanish, Portuguese and Hindi stayed within of English
What it means for you
For a team picking a voice agent to handle calls outside English, a single English-only completion score now hides which languages actually work, so a vendor's headline number can mask a system that drops replies in Korean or talks over callers in Mandarin, and a buyer serving Asian markets has to check language specific scores before signing a contract rather than trusting one blended figure.
In more detail
Researchers extended an existing English voice-agent benchmark, tau-Voice, into a new multilingual version called tau-Multilingual, adding Spanish, Brazilian Portuguese, Hindi, Korean and Mandarin with native speaker review of both the generated language and the spoken output. The paper was submitted on September 21, 2026, and evaluates several voice agents, including Grok, on 4,500 full-duplex phone calls spread across five voice configurations.
The results split cleanly into two groups. Spanish, Portuguese and Hindi stayed within 3.2 task-completion points of English performance, a gap the authors treat as close enough that those languages behave much like the English baseline. Korean and Mandarin did not: Korean task completion fell by 14.7 points and Mandarin by 8.4 points against the same English reference. The paper also separates out why each language struggled rather than reporting one number. Korean systems missed more responses outright, while Mandarin systems interrupted callers more often mid turn, and both languages produced more errors handling tools and named entities than the higher-scoring group did.
Grok’s own results cut against a simple headline. The paper reports that Grok leads on task completion across the tested systems, meaning it gets the call’s job done more reliably than the other agents evaluated. But on generation quality, the score covering how natural and accurate the spoken language itself is, Grok scores lowest among the systems tested. The authors argue this split is exactly why task, interaction and generation need to be reported as separate numbers rather than folded into one score: a system can finish a caller’s request while producing speech that a native reviewer would mark down.
Alongside the benchmark, the authors say they are releasing the language packs, the validated judges used to score each call, and supporting tools so other teams can build and run their own multilingual voice-agent evaluations rather than depending on a single lab’s English-only numbers.
The numbers
The 4,500 calls, the 3.2-point near-English cluster, and the 14.7 and 8.4-point drops for Korean and Mandarin are the core comparison points a reader evaluating a voice agent for non-English markets needs before trusting any single blended accuracy claim a vendor publishes.
Sources
Sources read
Cite this
AI Journey, "Paper Benchmarks Grok's Voice Agent Across Five Languages", 1 Oct 2026, https://aijourney.space/updates/2026-10-01-tau-multilingual-benchmarking-voice-agents-across-languages/ (source: arXiv, verified 1 Oct 2026)
Next in the stream
Anthropic's Claude Opus 5 Tested in New Post-Training Delivery Benchmark
Anthropic's Claude Opus 5 was one of four frontier agents tested in a new benchmark measuring whether an AI agent can be trusted to deliver a fine-tuned model, not just raise a metric.
Previous
Anthropic Releases Claude Opus 5.5 With Lower Prices
Anthropic released Claude Opus 5.5 on September 22, 2026, cutting per-token API prices and raising subscription usage limits for Claude users.
Next
More in xAI
xAI Changes Grok Pricing Page at grok.com
xAI's public site at grok.com now shows a pricing page that differs from the version this site last recorded, though the vendor has not detailed the change.
arXiv Paper Finds Grok Amplifies Aggression in Synthetic Cyberbullying Data
A new arXiv paper compared cyberbullying dialogues generated by Grok, GPT and LLaMA against real conversations, finding xAI's model stands out for amplifying aggressive behavior.