What happened
Published here
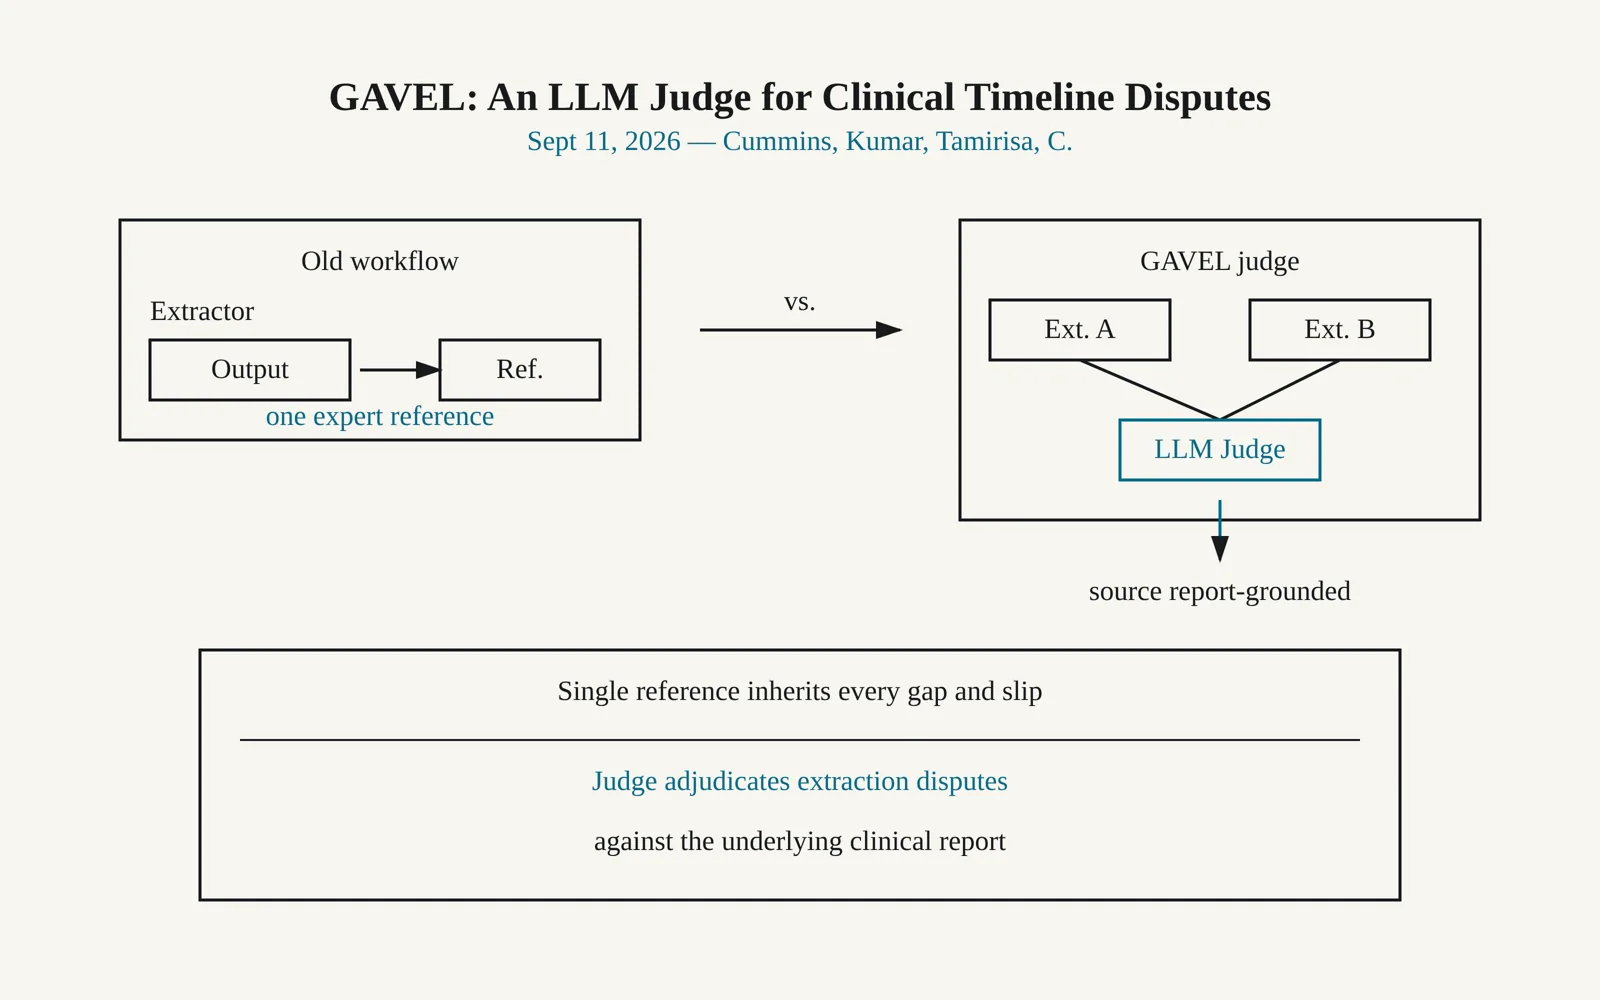
On September 11, 2026, researchers Jack Cummins, Sayantan Kumar, Ketan Tamirisa, and Jeremy C. Weiss submitted a paper describing GAVEL, a protocol that has a large language model compare two extracted clinical timelines against the original case report and rule on each discrepancy rather than scoring output against a single fixed reference annotation. (arXiv preprint 2609.13475, submitted 11 September 2026)
Open the photograph at full size
Photograph: Diagram: AI Journey
Read the full description of this diagram
Diagram drawn for this item: GAVEL Paper Proposes LLM Judge to Adjudicate Clinical Timeline Extraction Disputes. On September 11, 2026, researchers Jack Cummins, Sayantan Kumar, Ketan Tamirisa, and Jeremy C Clinical NLP teams building extraction pipelines usually validate against one expert-written reference, a workflow that inherits every gap and slip in that annotation; a report-grounded judge instead lets two competing extractors...
The numbers
Findings reviewed
2,738
Discrepancy findings manually reviewed from GPT5.6sol and DeepSeek V3.2 outputs
Merge preference rate
77.0%
Share of comparisons across 126 reports where the merged timeline was preferred
Discrepancies before merge
7.63
Average discrepancies per report attributed to the evaluated timeline before GAVEL-guided merging
Discrepancies after merge
0.85
Average discrepancies per report after GAVEL-guided merging
Read from arXiv preprint 2609.13475, submitted 11 September 2026
What it means for you
Clinical NLP teams building extraction pipelines usually validate against one expert-written reference, a workflow that inherits every gap and slip in that annotation; a report-grounded judge instead lets two competing extractors, including outputs from DeepSeek V3.2, be checked against the primary text itself, which changes how a team decides whether to trust or merge a pipeline's output.
In more detail
GAVEL, short for Grounded Adjudication of Variations across Extracted TimeLines, is a protocol described in a paper submitted to arXiv on September 11, 2026, and accepted for the AMIA Informatics Summit 2027. Instead of scoring an extraction pipeline against one expert-written reference timeline, the method has a large language model act as a judge: it reads the original case report alongside two competing timelines and returns a discrepancy type, a verdict, and the exact passage in the report that supports its ruling for every difference it finds.
The authors tested the judge’s own event matcher first, since a comparison protocol is only as good as its ability to line up the same clinical event across two differently structured timelines. They then applied GAVEL to outputs from GPT5.6sol and DeepSeek V3.2, along with timelines from other extractors and from human annotators, reading and confirming the judge’s rulings by hand rather than trusting them outright.
The numbers
The authors reviewed the judge’s output on 2,738 findings drawn from GPT5.6sol and DeepSeek V3.2 timelines, then had people confirm 89.4% and 88.6% of those rulings on manual check, a gap that shows the judge is usable but not infallible. A confidence threshold set at 0.10 split the matcher’s true match rate into 60% below the cutoff and 48% above it, evidence the boundary itself needs tuning rather than treating any single cutoff as settled. Across 126 case reports, timelines that GAVEL helped merge were preferred over either original in 77.0% of comparisons, with a 95% confidence interval running from 69.8% to 84.1%. Merging also cut discrepancies attributed to the evaluated timeline from 7.63 per report down to 0.85.
That drop matters for a specific workflow choice: teams building clinical timeline extractors currently have to pick one output and accept whatever errors its single reference annotation missed. GAVEL’s report-grounded merging offers a way to combine two candidate timelines, including one built on DeepSeek V3.2, into something closer to what the case report actually supports, without ever declaring either input the ground truth. The paper frames this as a general evaluation and revision tool rather than a one-off benchmark result, which is the more consequential claim for anyone deciding whether to adopt an LLM-judge step ahead of manual chart review.
Sources
Sources read
arXiv preprint 2609.13475, submitted 11 September 2026 (arxiv.org)
Paper read
Cite this
AI Journey, "GAVEL Paper Proposes LLM Judge to Adjudicate Clinical Timeline Extraction Disputes", 16 Sep 2026, https://aijourney.space/updates/2026-09-16-grounded-adjudication-of-variations-across-extracted-timelines-gavel-com/ (source: arXiv, verified 16 Sep 2026)
Next in the stream
Gemini subscription page keeps its prices and states a 5 hour limit refresh
Our poll found Google's United States subscription page changed. The prices our table records still stand, and the page states how the Gemini usage limit refreshes.
Previous
LayerRoute paper shows layer-skipping router matches wallclock speedup across ten training seeds
A single-author arXiv paper tests layer-skipping for efficient inference, the kind of cost problem answer engines like Perplexity AI's face at scale.
Next
More in DeepSeek
Paper Tests Whether DeepSeek Models Earn Predictive Credit for Explanations
A new paper tests whether DeepSeek's models add real predictive value when research agents explain planned experiments, not just describe them.
DeepSeek Cloud Model Ties Local LLM in Compliance Extraction Test
A paper posted to arXiv found DeepSeek's cloud API performed statistically the same as a locally hosted model at pulling compliance records from Vietnamese documents.