Event Published ResearchPerplexity AI
LayerRoute paper shows layer-skipping router matches wallclock speedup across ten training seeds
A single-author arXiv paper tests layer-skipping for efficient inference, the kind of cost problem answer engines like Perplexity AI's face at scale.
What happened
Published here
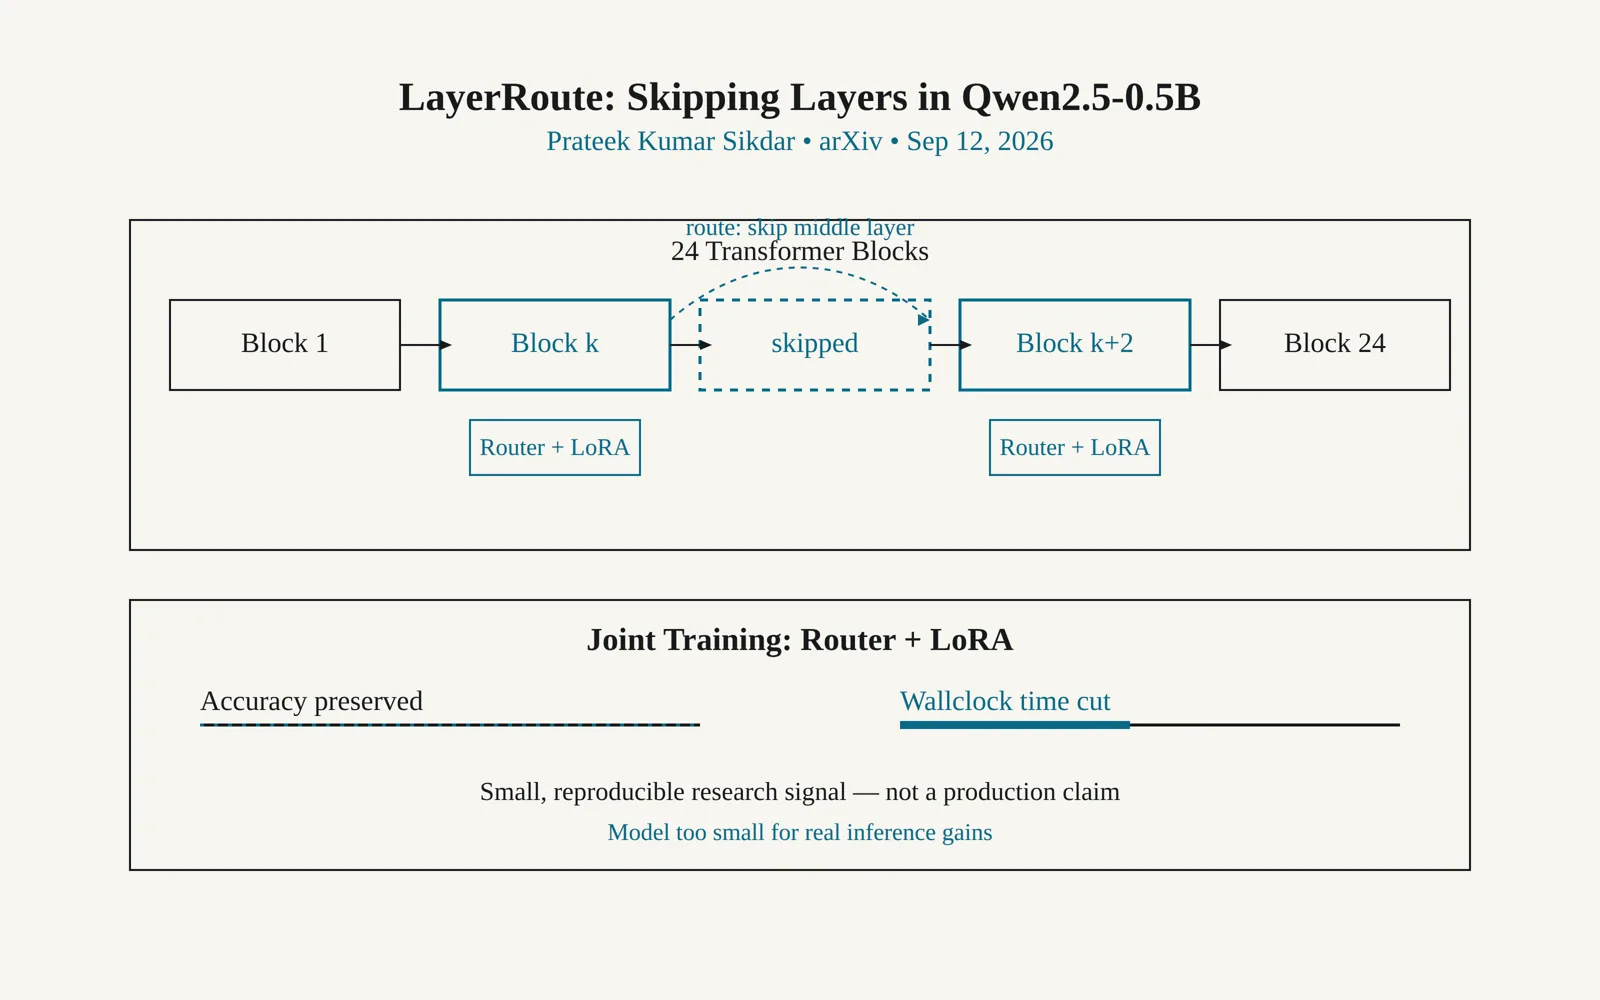
A paper titled LayerRoute, submitted to arXiv on September 12, 2026, describes a method for skipping transformer layers during inference without retraining a model from scratch. The author added a small per-layer router and LoRA adapters to Qwen2.5-0.5B-Instruct, a 24-block open model, then trained the router and adapters together so the router learns which layers a given input can skip. The paper reports results across ten independently seeded training runs rather than a single one, which is the detail that makes the claim checkable. (LayerRoute paper on arXiv, submitted September 12, 2026)
Open the photograph at full size
Photograph: Diagram: AI Journey
Read the full description of this diagram
Diagram drawn for this item: LayerRoute paper shows layer-skipping router matches wallclock speedup across ten training seeds. A paper titled LayerRoute, submitted to arXiv on September 12, 2026, describes a method for skipping transformer layers during inference without retraining a model from scratch. Inference cost is the daily bill for any product that answers questions by running a language model on every query, which is the business Perplexity AI is in.
The numbers
Wallclock speedup
1.02x-1.06x, mean 1.04x
Range and mean across ten seeded training runs
Perplexity delta
-1.16 and -1.11
Mean change across the two evaluation splits used
Training time
under 7 minutes
Router and adapter training on a single A100
Read from LayerRoute paper on arXiv, submitted September 12, 2026
What it means for you
Inference cost is the daily bill for any product that answers questions by running a language model on every query, which is the business Perplexity AI is in. A router that reliably skips a fixed block of middle layers without hurting output quality points at a cheaper way to serve the same model, though this result comes from a 0.5-billion-parameter model and has not been shown at the scale production answer engines actually run.
In more detail
The numbers
The router sits on top of Qwen2.5-0.5B-Instruct, a model built from 24 transformer blocks. The author added a lightweight router to each block along with LoRA adapters, then trained both jointly using a straight-through estimator so the router’s skip-or-run decision could be learned rather than fixed by hand.
The result the paper leans on is consistency. The router converged on the same structure in each of ten independently seeded training runs: a set of nine middle layers, numbered eight through sixteen, became eligible to skip in every run. That repetition across seeds is what the author uses to argue the pattern reflects something real about the model rather than an artifact of one training run.
Wallclock speedup across those runs measured 1.02x-1.06x, mean 1.04x, and the paper describes it as verified rather than estimated from a theoretical layer count. Quality held up alongside the speedup: joint LoRA adaptation produced a perplexity improvement over the unmodified backbone in every seed, with a mean delta of -1.16 and -1.11 across the two evaluation splits the author used. The router was also checked for whether it does real work rather than settling into a fixed pattern: its gate decisions changed the actual skip-or-run outcome for a large majority of held-out samples, which the paper reads as evidence of genuine input-dependent routing.
The whole setup is cheap to train. The paper reports the router and adapters training in under 7 minutes on a single A100 GPU, with negligible overhead added beyond the routing decision itself.
Why it matters for now
This is one paper on one small open model, not a deployed system, and the author is not affiliated with any of the companies tracked on this site. But the problem it addresses, cutting the compute an answer engine spends per query without degrading answers, is the same problem behind every consumer product that runs a model live against user questions, including Perplexity AI’s search product. The gap between a 0.5-billion-parameter research result and a production-scale deployment is wide, and nothing here shows the same skip pattern holds on the larger models those products actually run. What the paper does add is a specific, checkable claim: skip these nine layers, keep the router, gain roughly 4% in speed with quality preserved rather than traded away. Whether that generalizes past the model tested is the open question worth watching, not the number itself.
Sources
Sources read
LayerRoute paper on arXiv, submitted September 12, 2026 (arxiv.org)
Paper read
Cite this
AI Journey, "LayerRoute paper shows layer-skipping router matches wallclock speedup across ten training seeds", 16 Sep 2026, https://aijourney.space/updates/2026-09-16-layerroute-adaptive-layer-skipping-with-lora-preserved-quality-for-effic/ (source: arXiv, verified 16 Sep 2026)
Next in the stream
GAVEL Paper Proposes LLM Judge to Adjudicate Clinical Timeline Extraction Disputes
A new paper submitted September 11, 2026 pits GPT5.6sol against DeepSeek V3.2 timelines and uses an LLM judge to arbitrate the differences.
Previous
University of Melbourne WMT 2026 submission distills Gemini output to fill Tok Pisin, Bislama and Solomon Pijin translation gaps
A University of Melbourne paper posted 2026-09-15 uses Google's Gemini to generate training text for Pacific creole domains no dataset covered.
Next
More in Perplexity AI
Perplexity AI Researchers Detail LoRA Recipe For Converting Four Language Models To Diffusion
A paper associated with Perplexity AI describes BYOD, a LoRA-only method that converts standard autoregressive language models into diffusion language models without full retraining.
Paper Proposes Message-Passing Method For Compressing LLM Weights
A new arXiv paper proposes a message-passing method for compressing large language model weights, the kind of efficiency work that underlies answer engines like Perplexity AI.
Researchers Publish S-SALAAD Framework For Sparse Large Model Inference
A new paper on compressing large models for edge devices matters to Perplexity AI and any company whose answer engine has to run inference away from a data center.