What happened
Published here
On October 9, 2026, researchers published MathVis, a benchmark of 512 tasks testing whether large language models can visualize frontier mathematical problems and reason using diagrams rather than only symbols, evaluating GPT-6-Astra, Claude Fable 5 and Gemini 3.1 Pro Preview against reference diagrams, executable TikZ or SVG code and atomic rubrics. (arXiv paper MathVis: Can AI Reason through Drawing?, submitted October 9, 2026)
Open the photograph at full size
Photograph: Diagram: AI Journey
Read the full description of this diagram
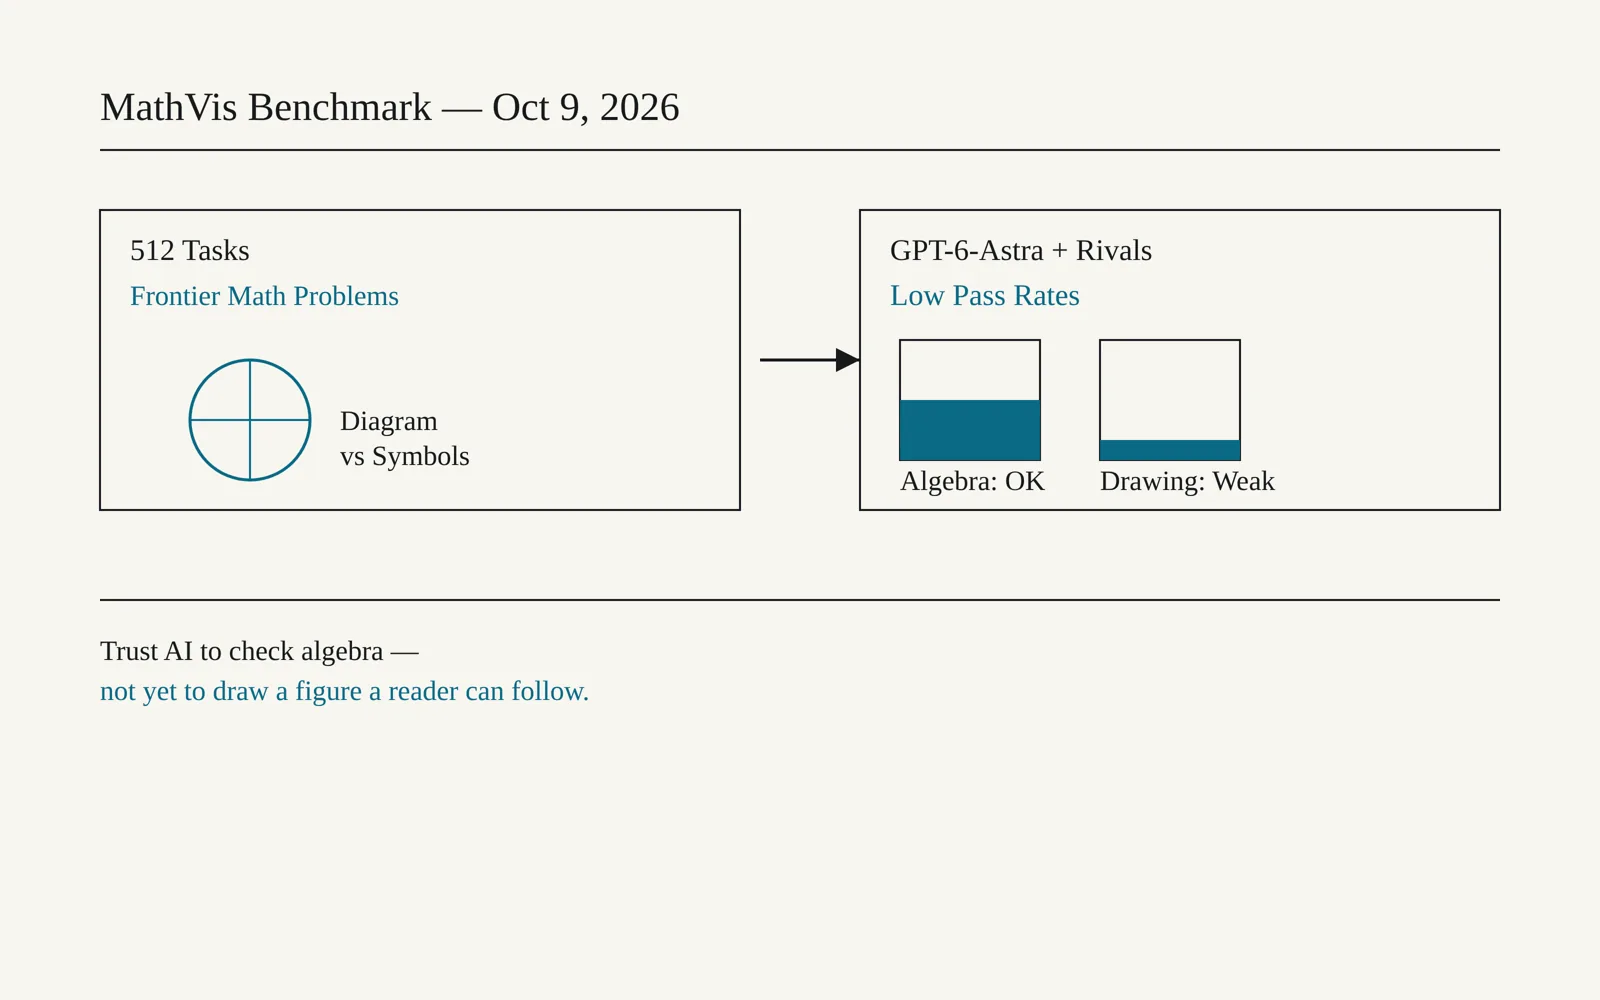
Diagram drawn for this item: New MathVis Benchmark Tests Claude and Rivals on Diagram Reasoning. On October 9, 2026, researchers published MathVis, a benchmark of 512 tasks testing whether large language models can visualize frontier mathematical problems and reason using diagrams rather than only symbols, evaluating GPT-6-Astra... For anyone deciding whether to lean on a chat assistant for geometry or visual proofs, the low pass rates say the tool is still better trusted to check algebra than to draw a figure a reader could follow, and a team building tutoring or...
The numbers
Benchmark tasks
512
Number of tasks in the MathVis benchmark
GPT-6-Astra pass@1
31.25%
Claude Fable 5 pass@1
26.56%
Gemini 3.1 Pro Preview pass@1
22.85%
Read from arXiv paper MathVis: Can AI Reason through Drawing?, submitted October 9, 2026
What it means for you
For anyone deciding whether to lean on a chat assistant for geometry or visual proofs, the low pass rates say the tool is still better trusted to check algebra than to draw a figure a reader could follow, and a team building tutoring or diagram-generation products on Claude now has a documented ceiling to plan around rather than a marketing claim to take on faith.
In more detail
A team of six researchers, led by Jingjing Wei, released MathVis on October 9, 2026, a benchmark built to answer a narrow question: can a model reason by drawing, not just by writing symbols. Each of the 512 tasks pairs a mathematical statement with a reference diagram, executable TikZ or SVG code, a Gold Intermediate Representation, atomic rubrics and error codes, so a grader can check whether a generated figure actually carries the reasoning a human mathematician would put on paper.
The headline numbers are modest across the board. GPT-6-Astra led with a pass@1 score of 31.25%, Claude Fable 5 followed at 26.56%, and Gemini 3.1 Pro Preview came in at 22.85%. None of the three cleared a third of the tasks on a first attempt, which the paper treats as evidence that visual reasoning on frontier mathematics remains a genuinely hard problem for current systems rather than a gap that will close with a minor prompt change.
What makes the result more pointed than a simple leaderboard is the explanation the authors give for the gap. They report that even when a model’s output technically contains every element a correct diagram needs, the LLMs tested lean on formal languages, symbols and graphics-program syntax rather than producing diagrams that mediate the reasoning step by step. The paper’s own phrase is that solutions are “often visually confusing to humans”, meaning a figure can pass an automated rubric while still failing the actual test a diagram is meant to serve, which is helping a person see the proof.
That distinction matters for anyone building on top of Claude, GPT or Gemini for education or technical writing tools. A model that writes correct TikZ code is not the same as a model that produces a diagram a student can read, and MathVis is designed specifically to catch that difference with its Gold Intermediate Representation and atomic rubrics rather than only checking final answer correctness.
The numbers
The benchmark’s 512 tasks span frontier mathematical statements requiring diagram-assisted reasoning. GPT-6-Astra scored 31.25% pass@1, Claude Fable 5 scored 26.56%, and Gemini 3.1 Pro Preview scored 22.85%, the three figures the paper reports from its evaluation.
The authors frame MathVis as a starting point rather than a finished scoreboard, saying the benchmark is meant to promote further work on letting models simplify their own reasoning through visual diagrams, an aim that puts the burden on future model releases to close a gap this paper has now measured in detail.
Sources
Sources read
arXiv paper MathVis: Can AI Reason through Drawing?, submitted October 9, 2026 (arxiv.org)
Paper read
Cite this
AI Journey, "New MathVis Benchmark Tests Claude and Rivals on Diagram Reasoning", 12 Oct 2026, https://aijourney.space/updates/2026-10-12-mathvis-can-ai-reason-through-drawing-a-benchmark-for-mathematical-figur/ (source: arXiv, verified 12 Oct 2026)
Next in the stream
Researchers Detail Byzantine-Resilient Defense For Federated Large Language Models
A new paper proposes a hypergraph defense for federated large language models, the kind of collaborative training an answer engine like Perplexity AI could one day rely on.
Previous
Stanford Team Publishes Next-Concept Modeling Paper on Faster Text Generation
Researchers tied to Perplexity AI's orbit published a paper describing Next-Concept Modeling, a coarse-to-fine method that generates text far faster than diffusion language models.
Next
More in Anthropic
Study Finds Precedent Labels Sway Claude Haiku Approval Calls
A new paper tests Claude Haiku 5.5 alongside other models on refund and claim decisions, showing that past case labels shift approvals sharply.
Paper Tests Claude Opus 4.8 Agents on Conflicting Code Edits
A new paper benchmarks Claude Code running Claude Opus 4.8 against other coding agents on tasks where two agents edit the same shared codebase at once.
Paper Finds Claude Opus 5.5 Agent Beats Automated CT Labeling Harness
A new paper testing CT scan labeling finds a free-form agent running Claude Opus 5.5 outscored an automated review harness on most of six public datasets.