Paper Details Low-Level Architecture For Spatial Agentic AI
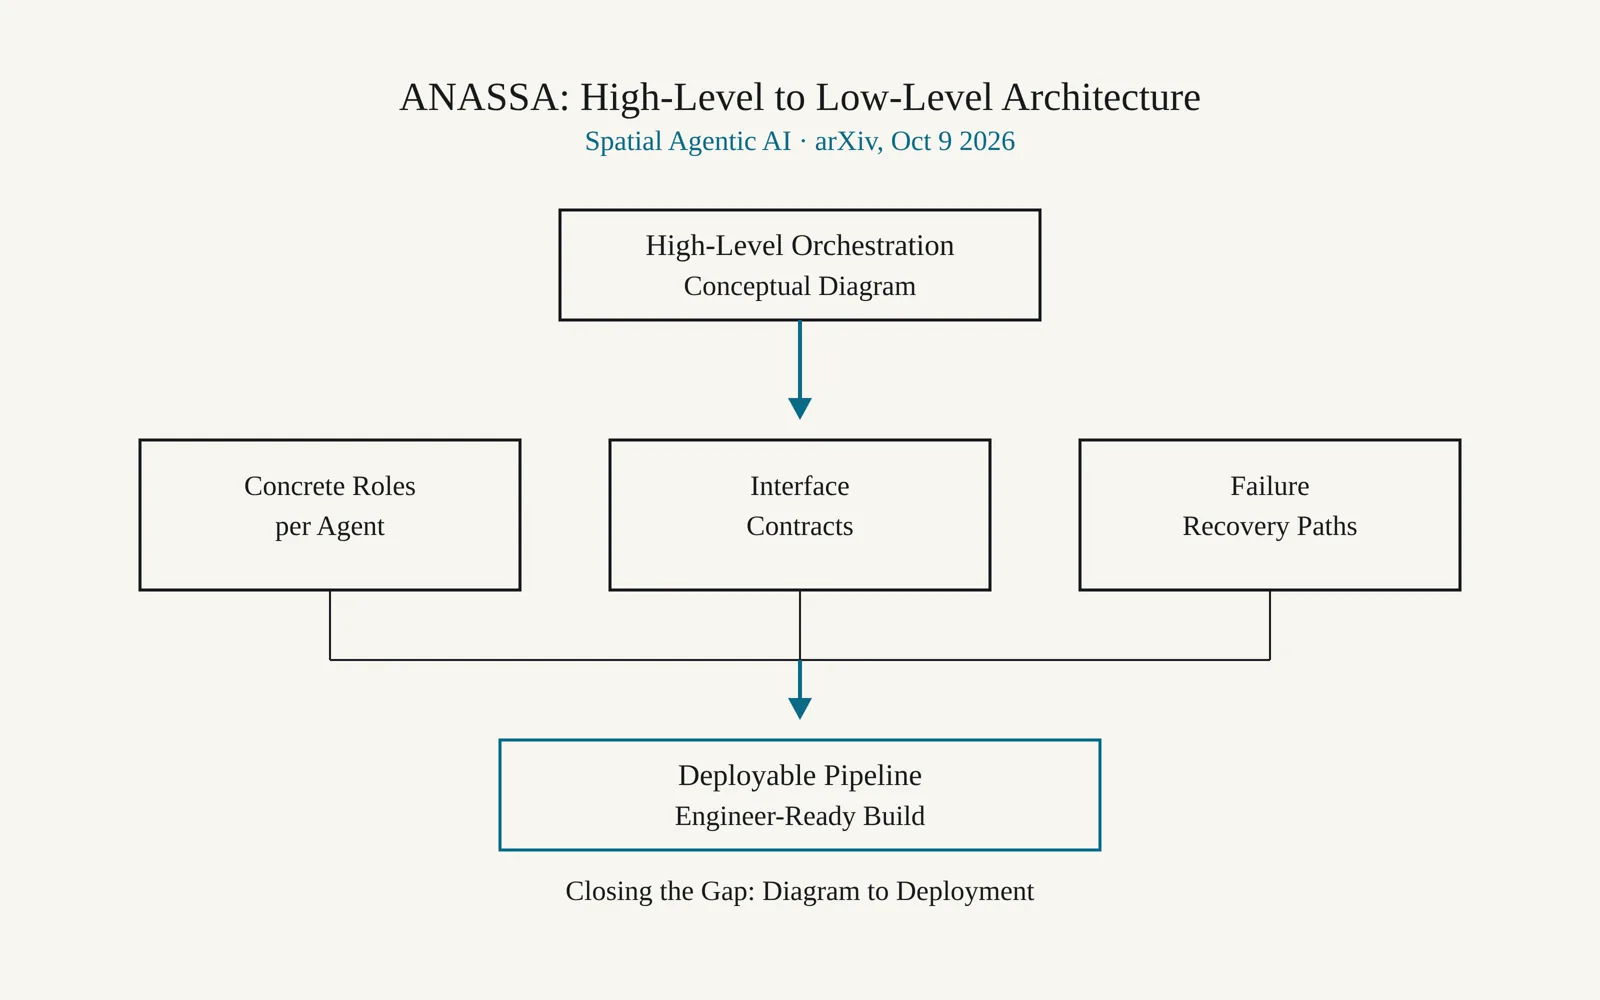
A new paper posted on arXiv breaks down the ANASSA framework for spatial agentic AI into an implementation-ready low-level architecture with named roles and contracts.
Older changes from the same sourced stream. This is page 7 of 16; each item remains listed in the month when it was published. Every row keeps its source, event date and plain account of what changed.
A new paper posted on arXiv breaks down the ANASSA framework for spatial agentic AI into an implementation-ready low-level architecture with named roles and contracts.
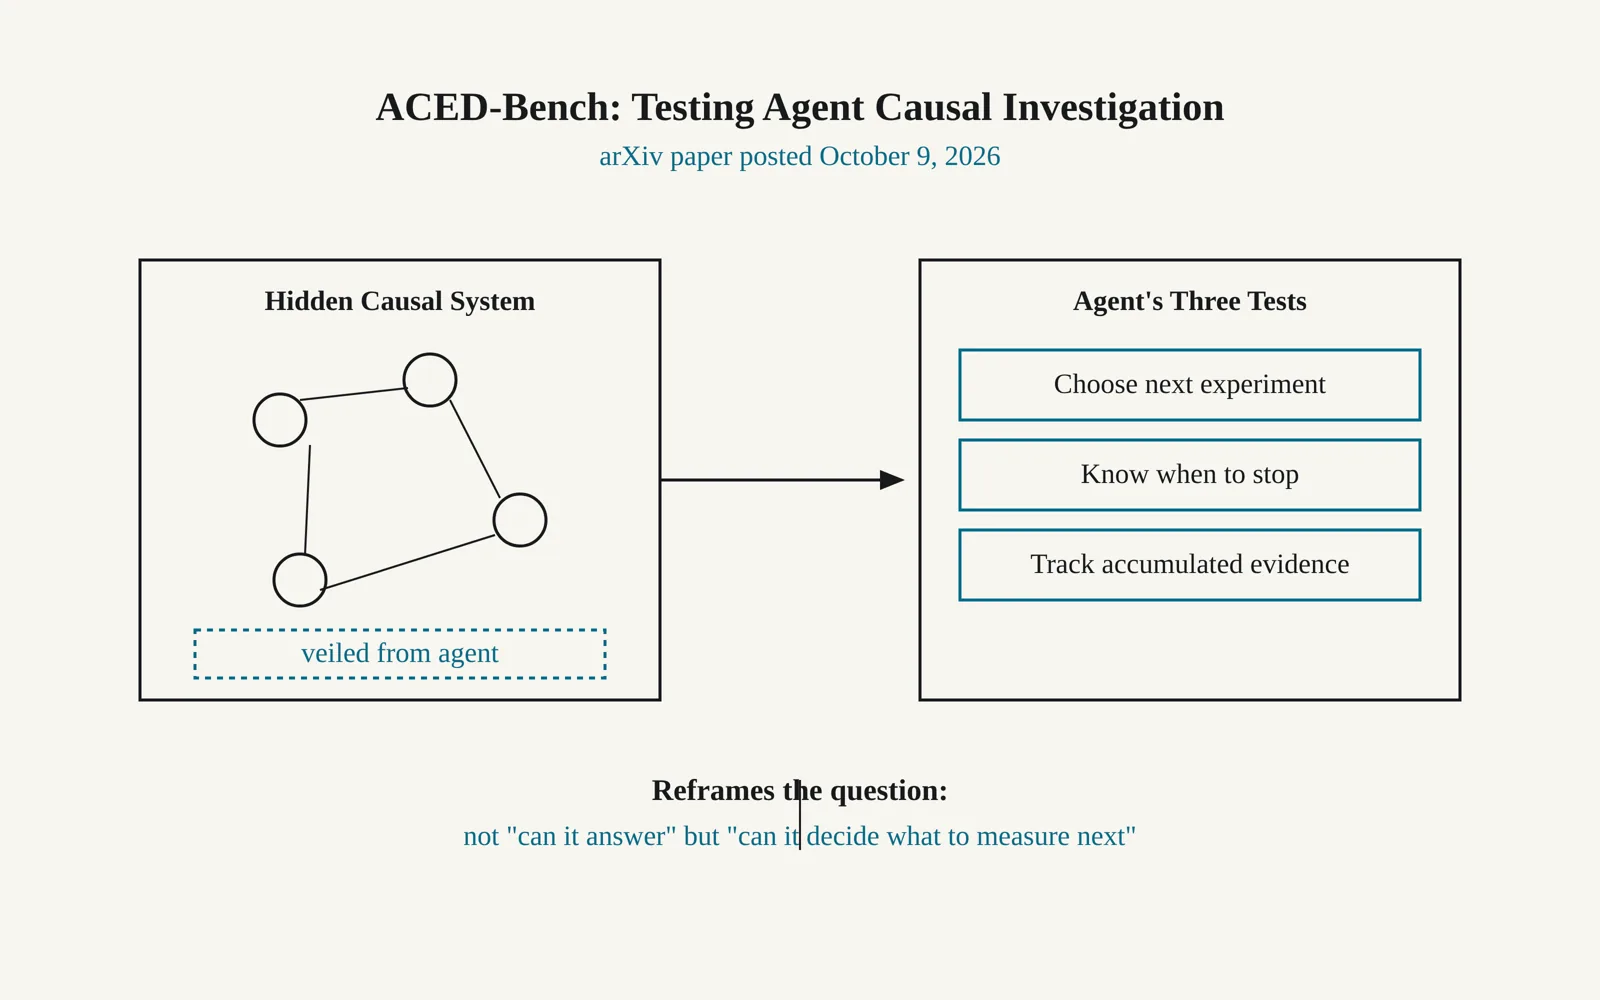
A new paper posted to arXiv introduces a benchmark that checks whether AI agents can gather causal evidence rather than just answer prompts.
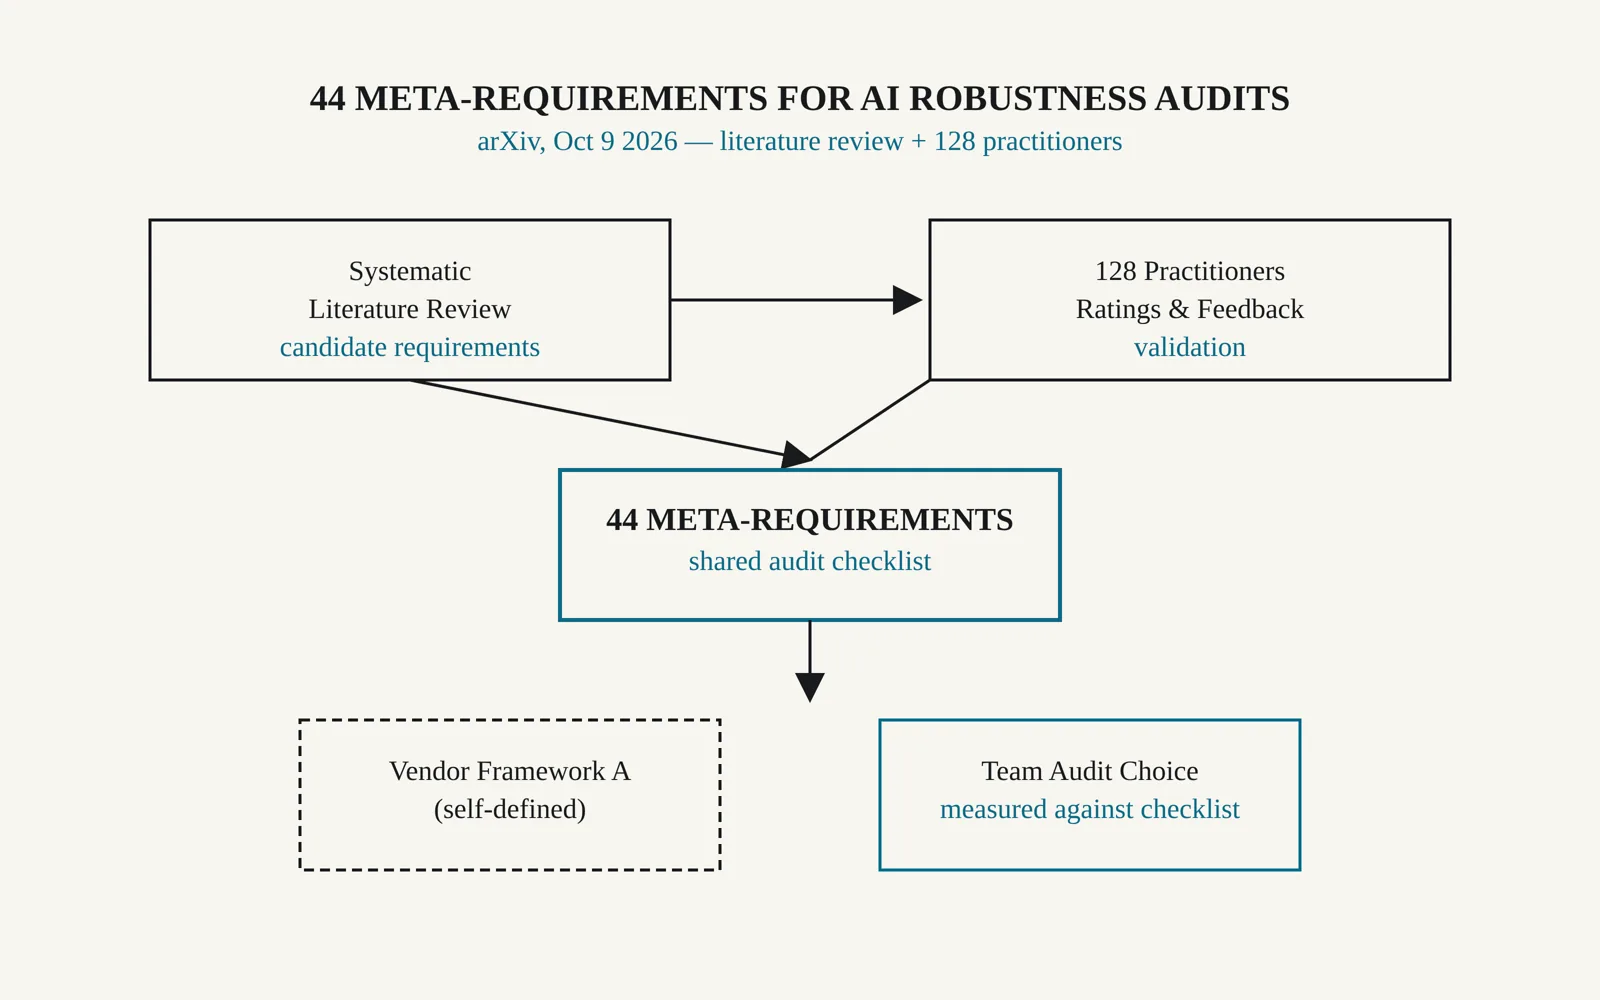
A new paper on arXiv proposes 44 meta-requirements that any AI robustness auditing framework should support, built from a literature review and validated by practitioners.
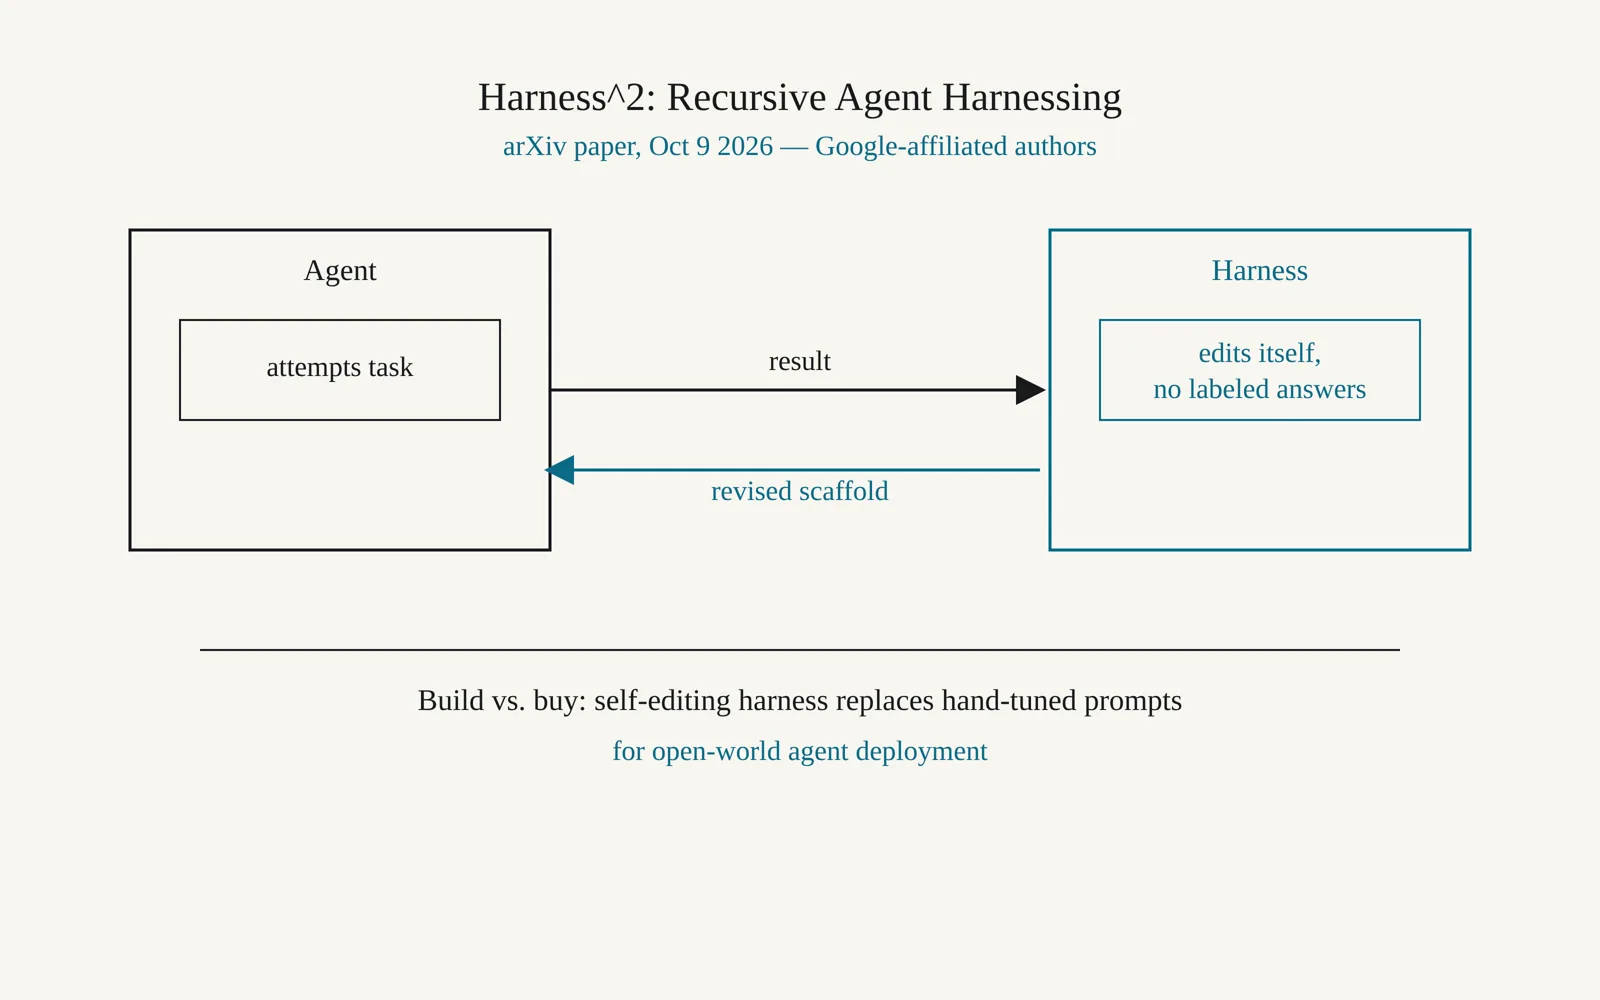
A paper with Google-affiliated authors proposes Harness^2, a framework that lets agent harnesses edit themselves and reports gains on Gemini 3.5 Flash.
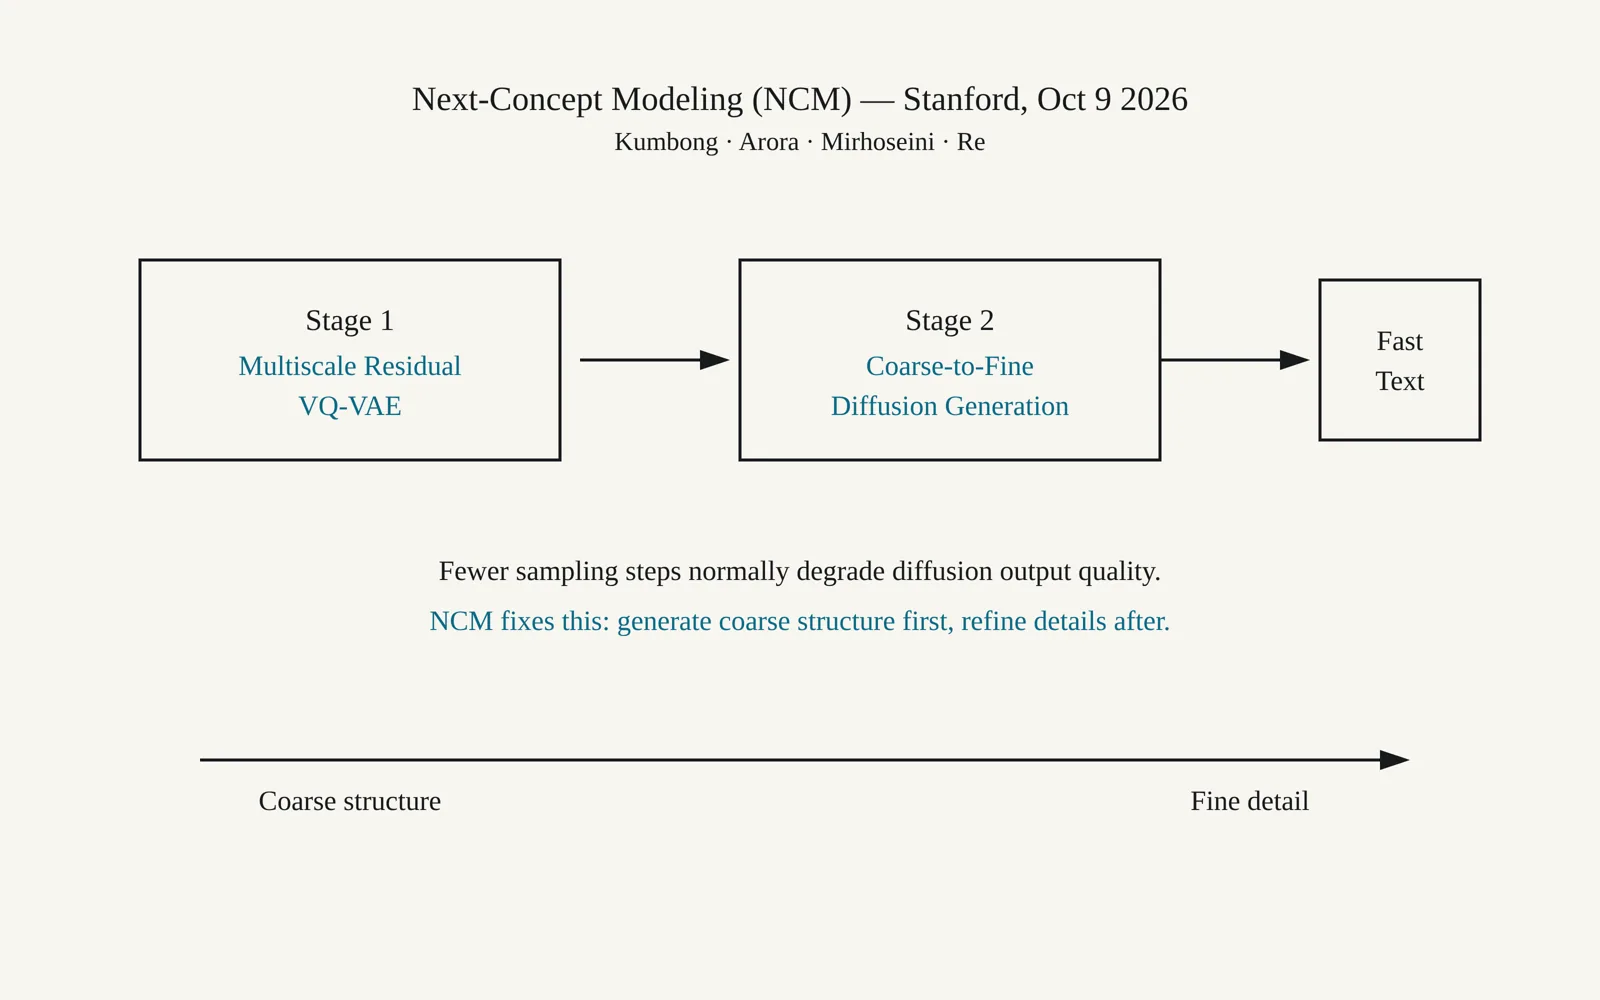
Researchers tied to Perplexity AI's orbit published a paper describing Next-Concept Modeling, a coarse-to-fine method that generates text far faster than diffusion language models.
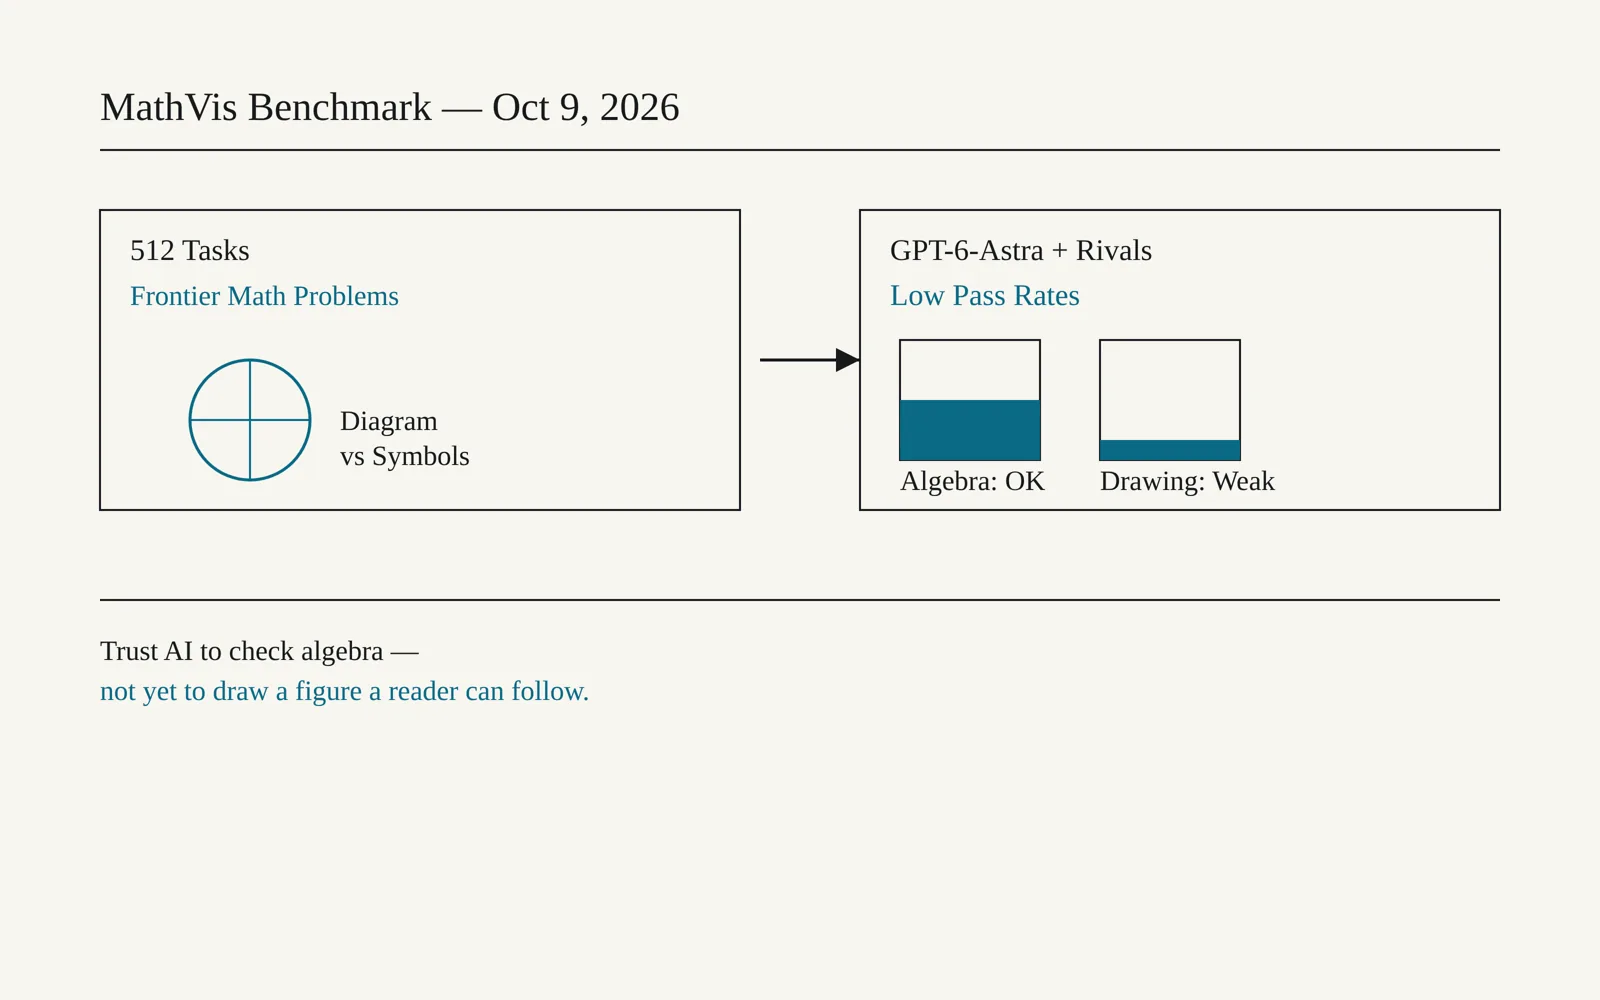
A new benchmark called MathVis found Claude Fable 5 and rival models struggle to reason through drawing on frontier mathematical problems.
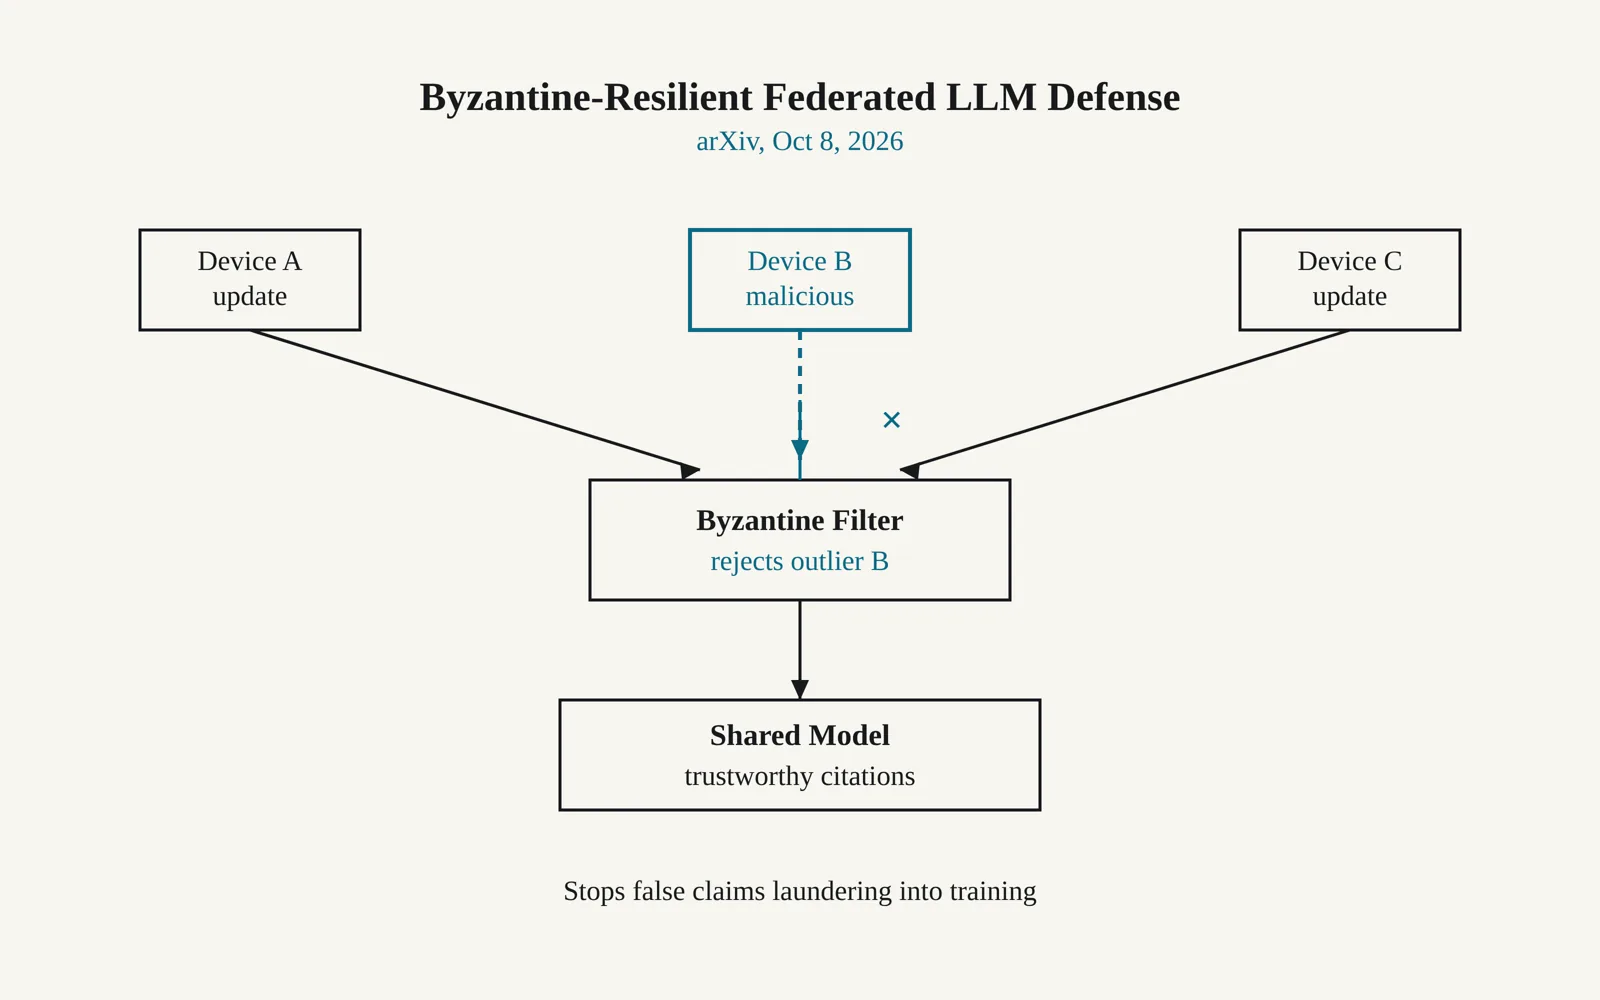
A new paper proposes a hypergraph defense for federated large language models, the kind of collaborative training an answer engine like Perplexity AI could one day rely on.
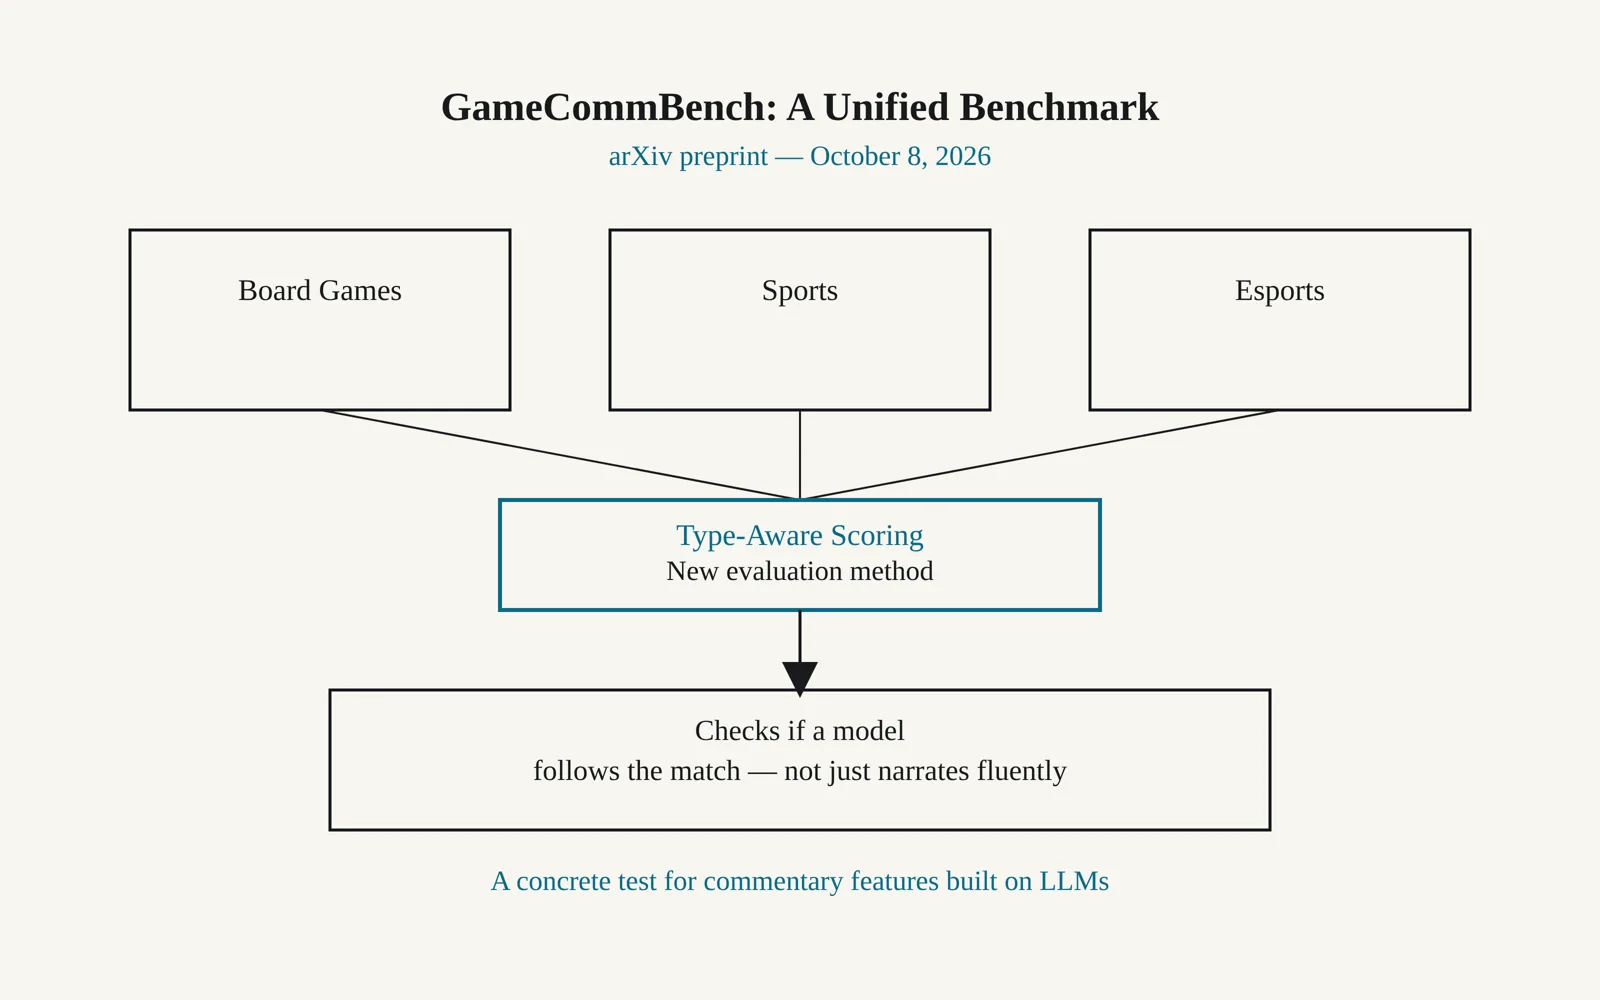
A new arXiv preprint introduces GameCommBench, a benchmark testing whether AI systems can produce usable live commentary across board games, sports and esports.
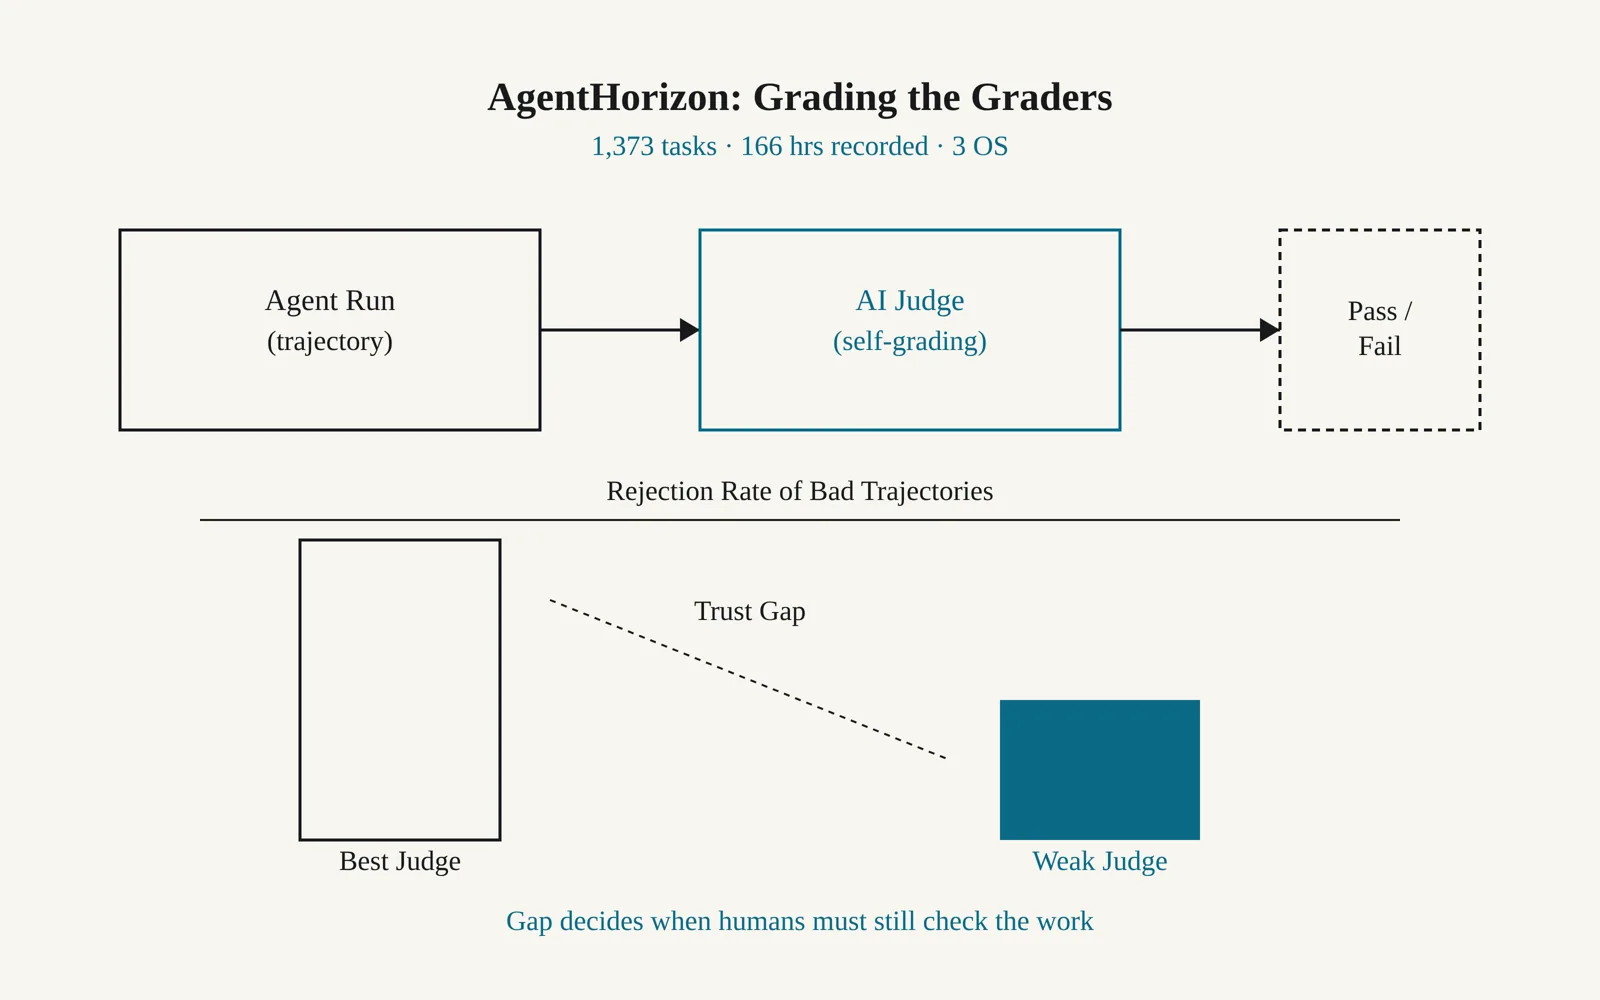
A new paper introduces AgentHorizon, a benchmark testing whether AI judges can spot failed long computer-use tasks that merely look complete.
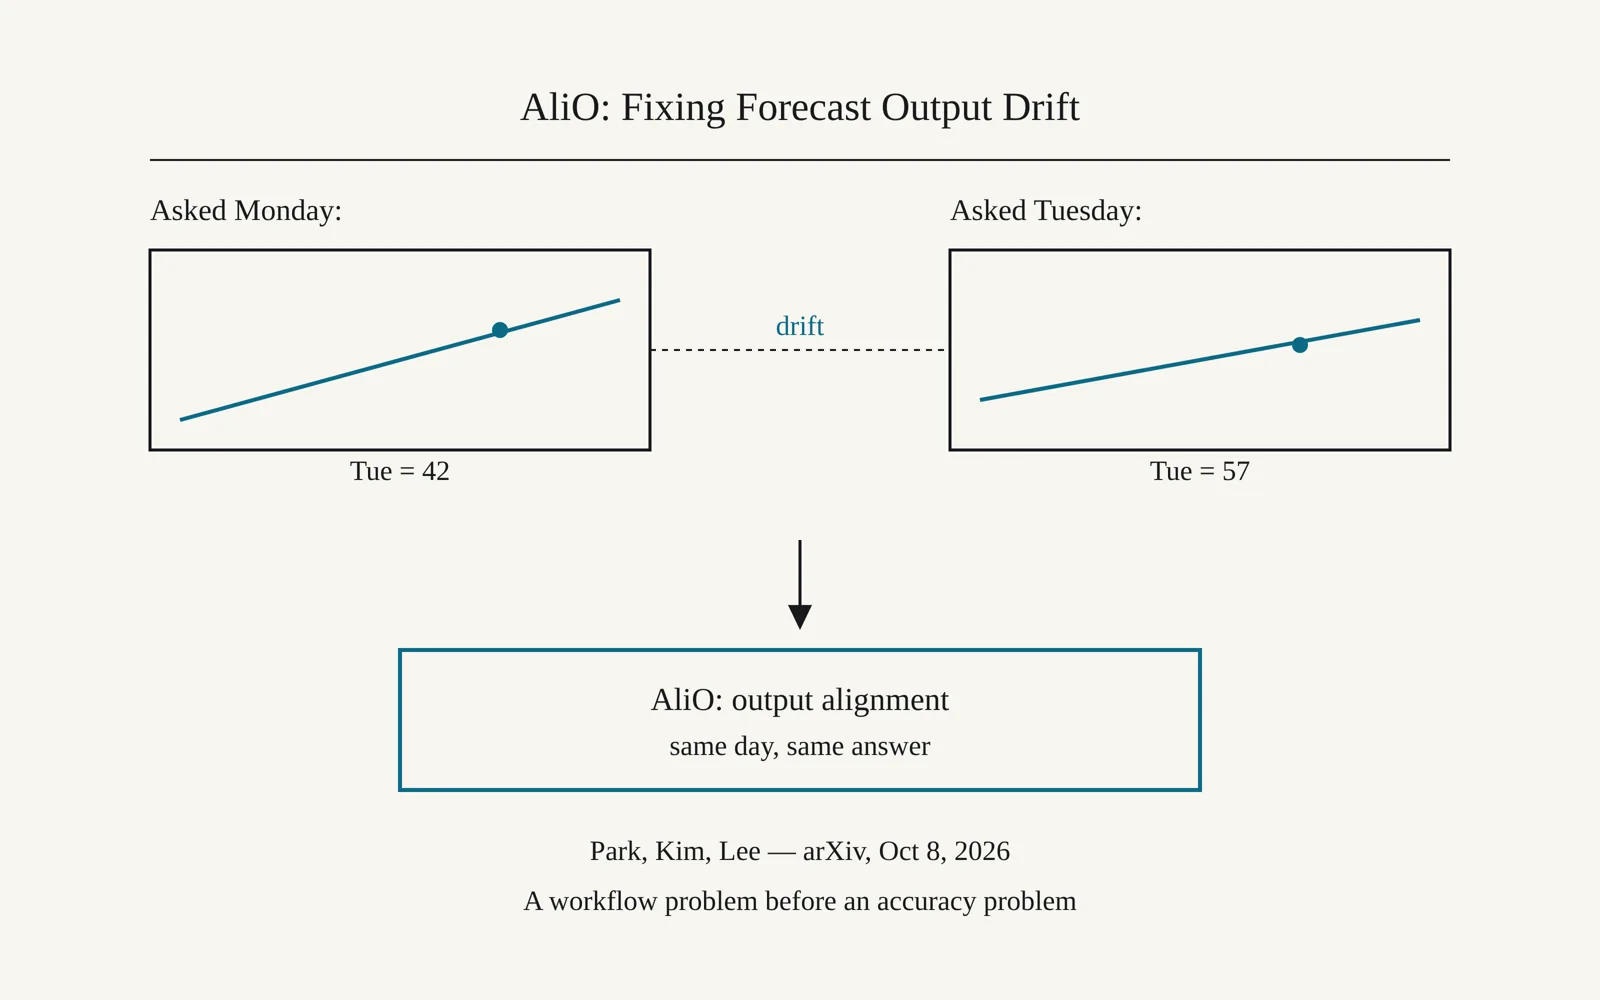
A new paper posted to arXiv finds that long-term time series forecasting models produce inconsistent predictions for the same timestamp and proposes a fix.
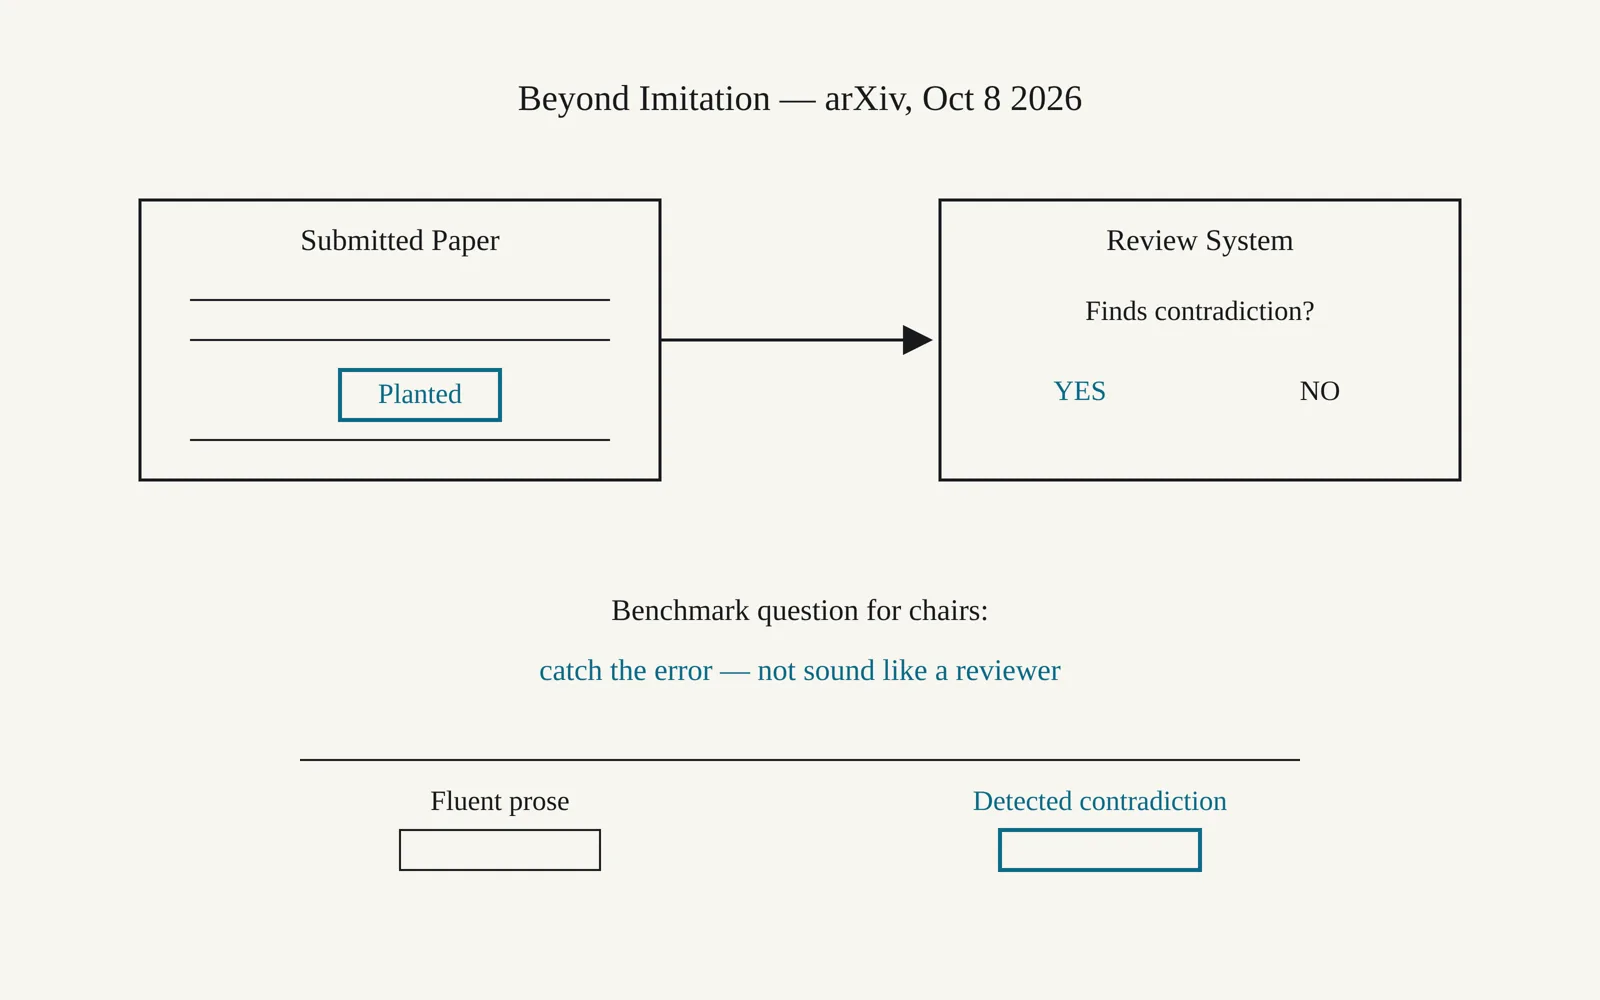
A new paper argues that testing whether language models can imitate reviewer prose misses the point, and proposes a benchmark built around catching planted errors instead.
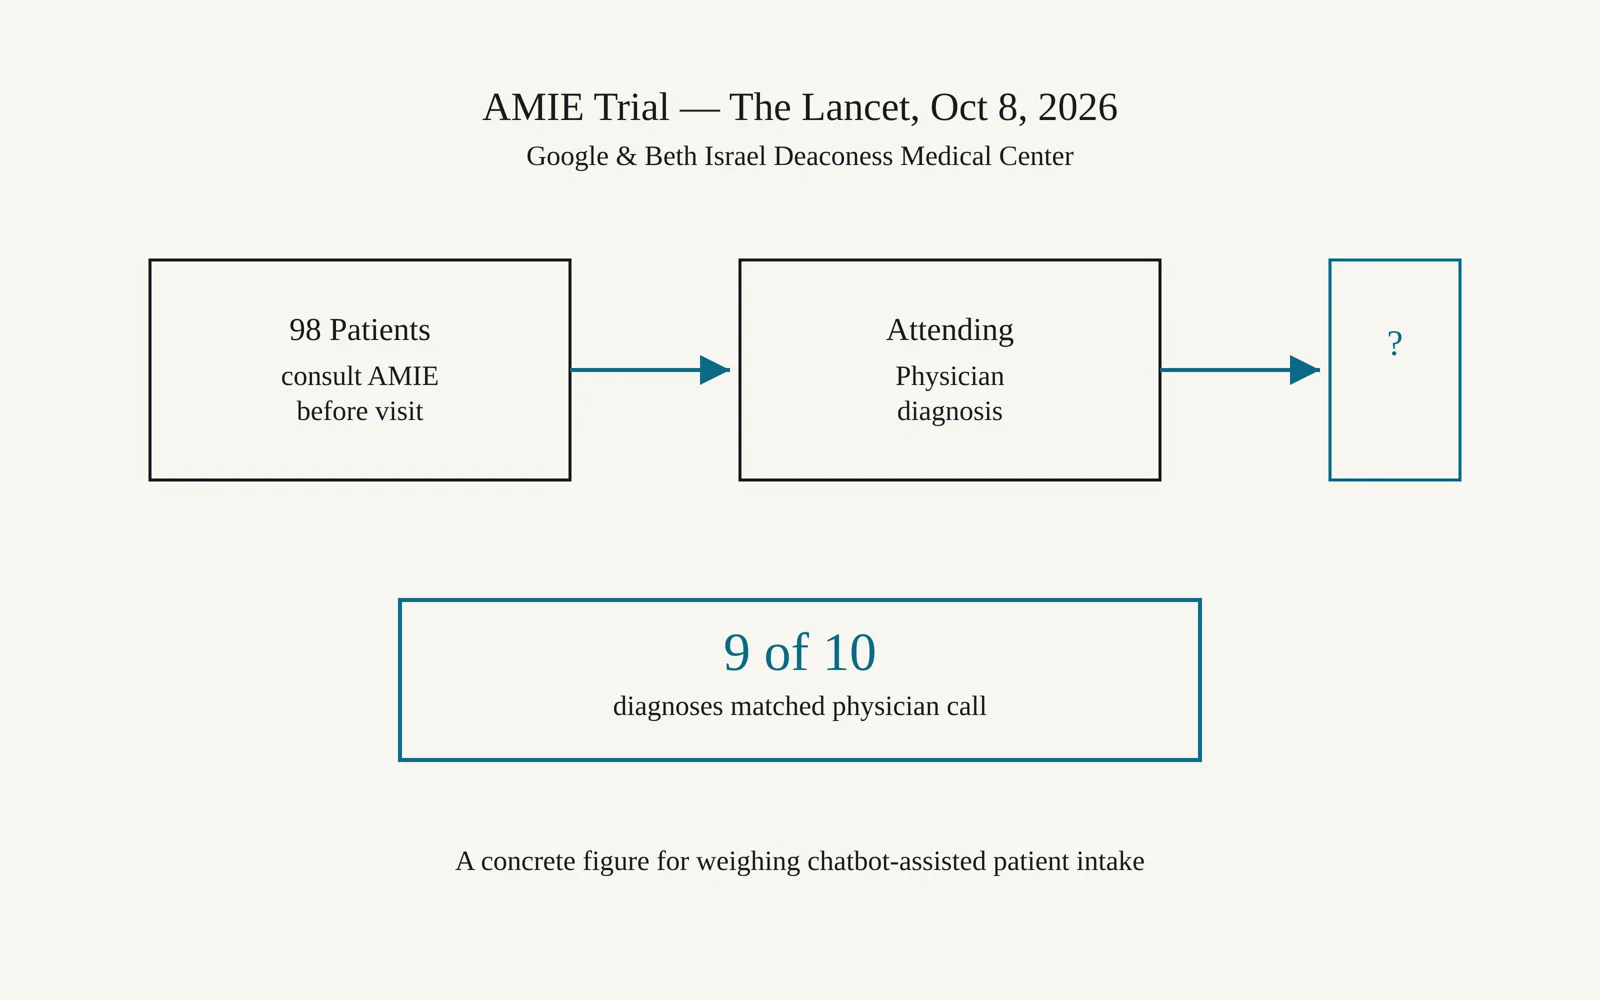
Google published a peer reviewed study in The Lancet describing how its AMIE research AI performed during real primary care visits at a Boston clinic.
This is a permanent listing in what changed in AI. Each item keeps its own page, source and dates. How the stream is made.